AI news
Joe Tsai at Wuzhen: 470+ Open Qwen Models, 4B Downloads, 330K Derivatives
Short answer
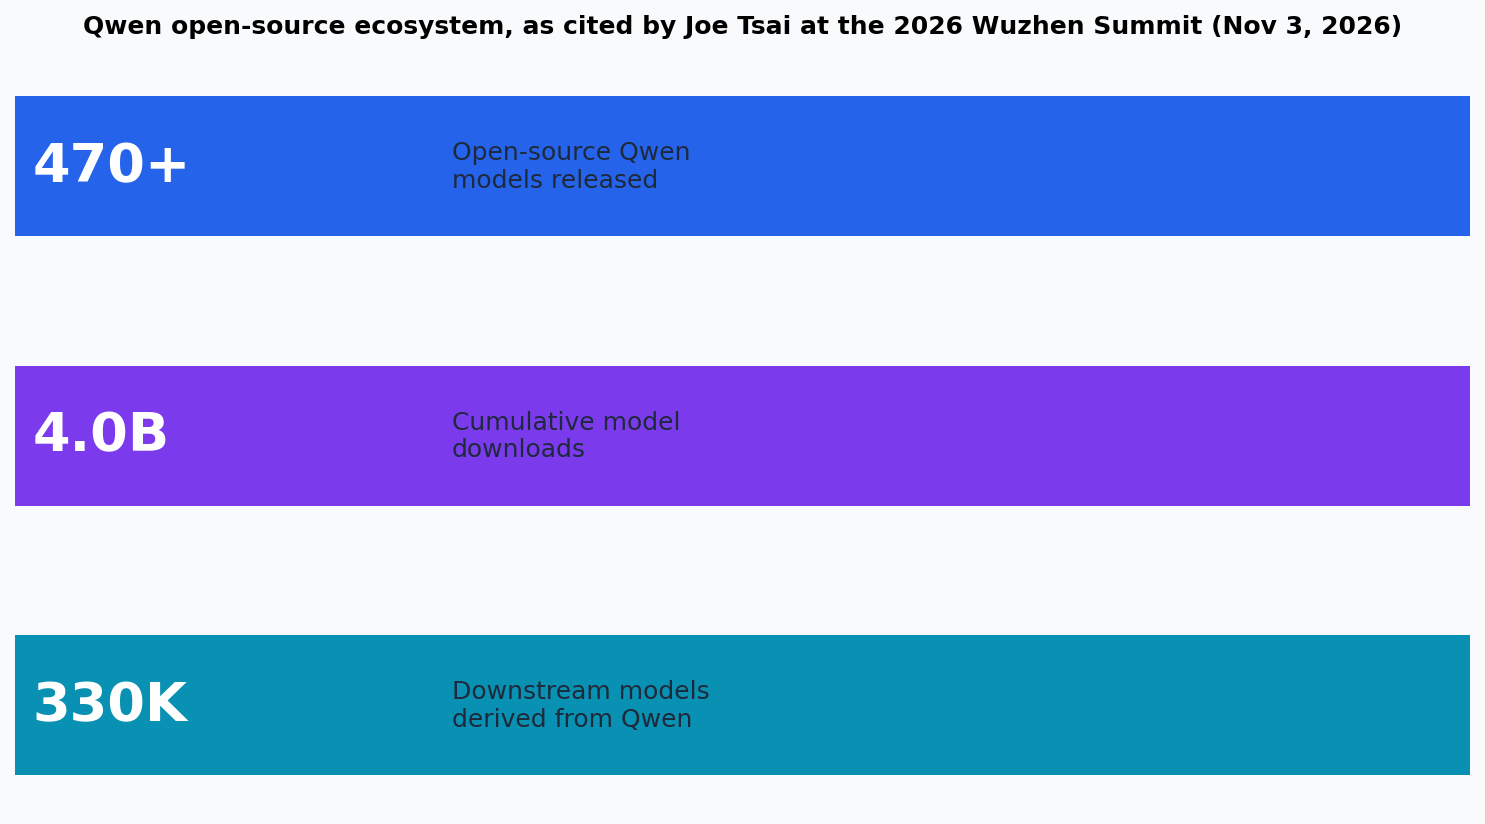
- At the Wuzhen Summit opening this morning (Nov 3), Alibaba chairman Joe Tsai put hard numbers on Qwen's open-source footprint: 470+ open models, 4 billion cumulative downloads, 330,000 derivative models — per on-site reporting from Jiemian News.
- We checked what we can check: the Qwen org on Hugging Face currently lists 469 public model repos, consistent with "more than 470" once ModelScope and other endpoints are counted.
- Why a busy developer should care: the derivative-model count is the signal here, not the headline number. A 330K-model downstream ecosystem means the Qwen architecture is the base everyone finetunes on — which is exactly what you want from a self-host base: tooling compatibility, quantized variants for every GPU tier, and someone who has already hit your exact bug.
The 2026 World Internet Conference in Wuzhen opened today with open source as the explicit theme — the summit's official topic this year is "openness and shared building" — and Tsai used the keynote to argue that open weights are the only realistic path to AI adoption at scale. His reasoning, per Jiemian's on-site report: AI demand keeps climbing while compute stays scarce ("supply falls short of demand" was his framing), and open weights are what let small and mid-sized companies actually afford R&D. He added that this matters most for developing countries — a pointed remark, given the summit's audience.
The three numbers he cited for the Qwen ecosystem:
The number we could verify, and the ones we take on citation
The "470+ models" figure is checkable, roughly. The Qwen organization on Hugging Face lists 469 public model repos as of this morning (pulled via mirror; HF is unreachable from our network directly). Add whatever is exclusive to ModelScope, Alibaba's own hub, and model-family repos that got merged or retired, and "more than 470" holds together. The 4-billion download figure spans both HF and ModelScope and we can't decompose it — treat it as a company-cited number, not an audited one.
The 330,000 derivative models is the most interesting claim precisely because it's the least like a vanity metric. Derivatives are other people's finetunes, merges, and quantizations built on Qwen bases. You can't inflate that number with press releases; it's a census of community work. For comparison's sake: this is the metric that made Llama the default self-host base two years ago, and DeepSeek's post-V3 open-weight releases started competing for the same slot. My read is that Qwen currently holds that "default base" position more firmly than either — the Apple Intelligence China deal leaned on exactly this ecosystem gravity (see our earlier piece on why Alibaba was the only answer for Apple's China beta).
What it changes for model selection — honestly, not much today
None of this is new pricing, a new checkpoint, or a new capability. If you're choosing between Qwen, DeepSeek, and Llama-family bases for a self-host stack this week, today's keynote doesn't move the needle on its own. What it does do is confirm the strategy: Alibaba intends to keep Qwen open across every size tier, and the derivative ecosystem around it is the deepest in open weights right now. If you already run Qwen, expect the quantization and finetune tooling around your stack to keep improving without your investment. If you're betting on a different base, the bar you need it to clear just got quantified.
We'll be watching the rest of the summit's 27 sub-forums — and whether DeepSeek uses the Wuzhen stage for anything beyond the inference-framework open-sourcing it announced just before the summit (we covered that separately when it shipped). Kimi's K3.1 Pro weights are also due tomorrow, Nov 4, per Moonshot's own timeline — that's a more concrete release to plan around than any keynote stat.
Speech content and the three ecosystem figures are as reported by Jiemian News on-site at Wuzhen on 2026-11-03 (via syndicated copies on Tencent News and 10jqka). The 469-repo count was pulled from the Qwen Hugging Face org via mirror on the same day. Speech figures are company statements, not audited metrics.
Sources: Jiemian News — Joe Tsai at Wuzhen (Tencent News syndication), Qwen org model listing (Hugging Face mirror, checked 2026-11-03)