DeepSeek
Kimi K3.1 Pro Is Worse on Purpose: Moonshot Scrubbed Its Cyber Skills Before Open Weights
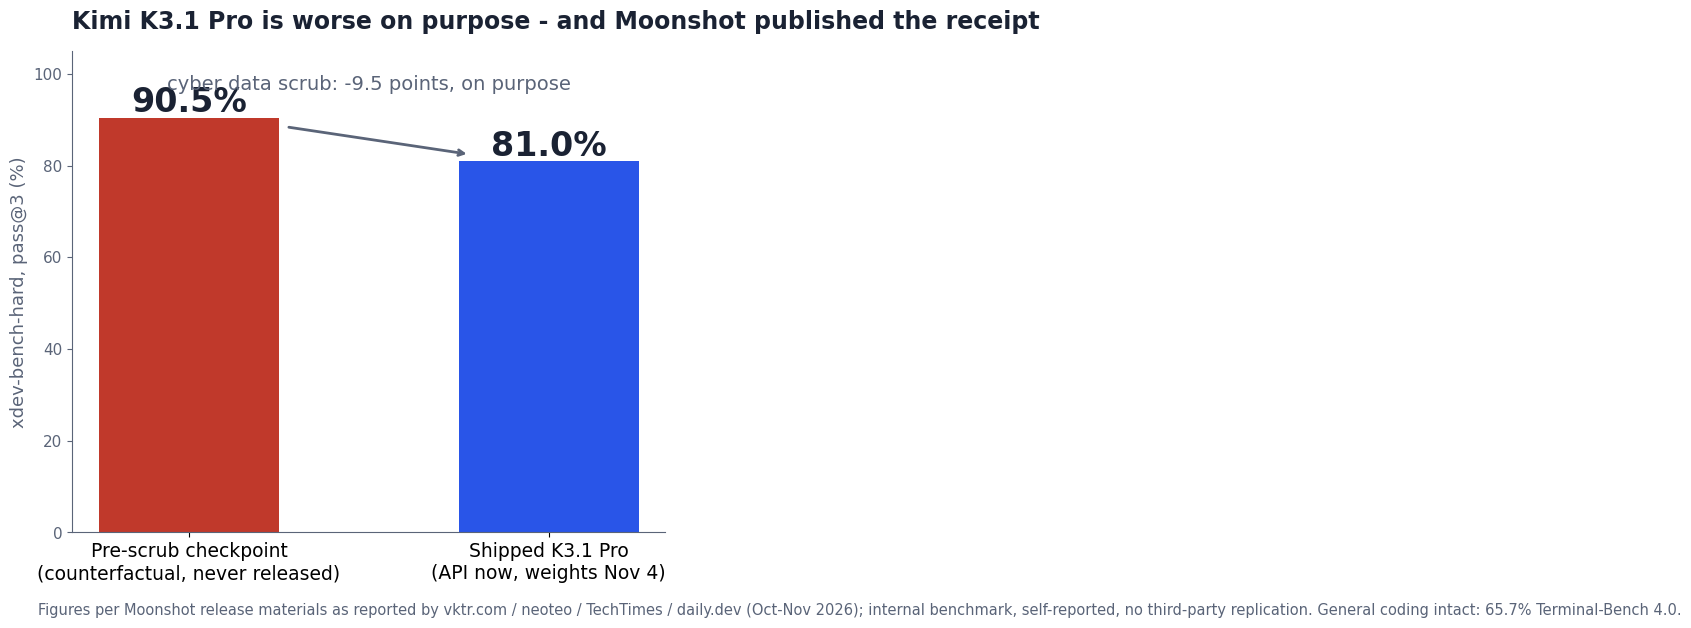
Verdict: Moonshot's Kimi K3.1 Pro is the first frontier-class model shipped deliberately weakened on purpose — and the company published the receipt. They removed cyber-related training data from both the mid-training and RL stages, which cut exploit-development success on their internal benchmark (xdev-bench-hard, pass@3) from 90.5% to 81.0%. General capabilities stay intact: 65.7% on Terminal-Bench 4.0, 0.7 points behind Claude Opus 5.5, at $2/$10 per million input/output tokens — a fifth of Astra's price. As of this writing (Nov 2), the full weights are still not out — I checked the moonshotai org on GitHub and the model hubs: no K3.1 Pro weight repo exists yet, with release promised by November 4. My call for self-hosters: this is a "wait for Friday" decision, not a "skip" decision — but set expectations now. The 90.5% checkpoint will likely never be released; what lands on Nov 4 is the 81% model, in a 2.8T-parameter MoE (104B active) you will not run at home anyway. For API users nothing changes — the model you call is already the scrubbed one.
Verified against primary sources (2026-11-02): GitHub API for org moonshotai — repos sorted by recent push show Kimi-K3 (created 2026-08-06), kimi-code, FlashKDA; no K3.1 Pro weight repository as of 2026-11-02; mirror-index model listing confirms no K3.1-Pro weights downloadable. Pricing $2/$10 verified in our K3.1 Pro vs GPT-6 Astra pricing piece (OpenRouter listing, official pricing page, cross-checked Oct 26). Reported (transcribed): cyber-removal figures 90.5%→81.0%, Terminal-Bench 4.0 65.7% (vs Opus 5.5 66.4, GPT-6 Astra 58.2), 2.8T/104B-active size, 1M context, Nov 4 weight deadline, and enterprise manual-enable gating per vktr.com, daily.dev, neoteo and TechTimes coverage (Oct 26 – Nov 1, 2026), all citing Moonshot's own release materials, which I could not fetch directly (HF connectivity blocked from this network). The 81.0% is pass@3 on Moonshot's internal exploit benchmark — team-chosen, self-reported, no third-party replication yet.
Caveat (dated 2026-11-02): The Nov 4 weight release is a company promise, not a shipped fact — this page does not track it. Accuracy as of publication date.
Kimi K3.1 Pro went live in the Kimi app and API in late October ( is when English coverage consolidated), and Moonshot did something almost no lab does: it shipped the model, published the benchmark chart showing how much capability it removed, and published the counterfactual — the number the unrestrained model would have hit. On xdev-bench-hard, Moonshot's internal source-code exploit benchmark, the pre-scrub checkpoint solves 90.5% of tasks at pass@3; the model you can actually use solves 81.0%. That 9.5-point gap is the price of the safety scrub, stated in the company's own numbers.
What exactly was removed — and why the honesty matters
The removal wasn't a refusal-tuning pass at the end. Moonshot traced vulnerability-research performance climbing as post-training scaled, found cyber content mixed into the general mid-training corpus and cyber tasks sitting in the RL environment mix, and then stripped cyber-related data from both stages — while keeping general-purpose coding work intact. That is a surgical change with a measurable cost, and publishing the counterfactual is the rare part. Most labs quietly ship the scrubbed model and let you guess. Whether you rate the decision itself or not, the reporting standard is the best I've seen from a Chinese lab this year, and it hands security researchers something to actually measure.
One caveat on that number, because it is the load-bearing figure in this story: 81.0% is pass@3 on Moonshot's own benchmark, chosen and scored by the team that built the model. There is no third-party replication yet. Treat both 90.5 and 81.0 as "company-reported with unusual transparency," not as audited facts.
What stays: frontier coding at a fifth of Astra's price
The scrub was targeted. K3.1 Pro still puts up 65.7% on Terminal-Bench 4.0 — 0.7 points behind Claude Opus 5.5 and well ahead of GPT-6 Astra's 58.2, per Moonshot's numbers as reported by English coverage. Pricing is $2 per million input tokens and $10 per million output — exactly a fifth of Astra's $10/$50, a fact we verified against OpenRouter and official pages in October. The spec sheet reads 2.8T total parameters in a Mixture-of-Experts layout with about 104B active, and a 1M-token context window. Artificial Analysis ranks it fourth on its Intelligence Index — which would make it the top open-weights model the moment weights actually land.
The weight situation as of today: promised, not shipped
The "open weights" part of this story is still a promise. I checked the moonshotai organization on GitHub and model-hub listings on November 2: there is no K3.1 Pro weight repository yet — the org's model repos top out at Kimi-K3 (which itself ships under a modified MIT license with safety constraints). Moonshot's stated deadline is November 4, and enterprise admins reportedly need to enable access manually even on the API side. So the timeline is: API already scrubbed, weights scrubbed-and-pending, and the 90.5% checkpoint almost certainly never ships.
For self-hosters doing the math at home: 2.8T total parameters is not a home-server model even with 104B active — this is a multi-GPU-rack release, like K3 before it. The realistic self-hosting play is waiting for quantized community builds or renting capacity from providers that serve the open weights. If you were hoping the weights would contain the un-scrubbed variant: no. What lands is the 81% model, and the license will carry safety constraints that bind lawful users (they never bind the adversaries the scrub is worried about — that tension is inherent to every open-weights safety story).
My one-liner: API users — nothing to decide, you were already getting the scrubbed model at a great price. Self-hosters — wait for Friday, download nothing on day one, and let someone else burn $32 discovering that self-reported benchmarks and KingBench runs don't always agree.
Related reading: Kimi K3.1 Pro vs GPT-6 Astra pricing, DeepSeek Search & Fetch billing math, Clover-35B diffusion LLM for agents, DeepSeek V4.1-Flash-1017 release notes.